Meet The LogicStar Team
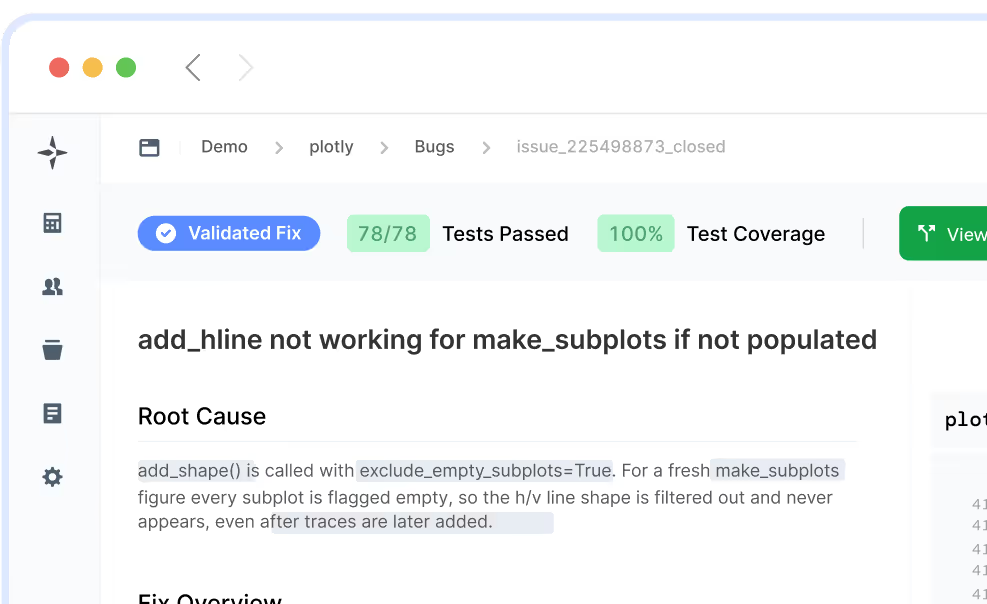
We make software engineering agents measurably better. We test them on your code and real engineering outcomes, find their blind spots, and measure whether each change actually improves them.


We make software engineering agents measurably better. We test them on your code and real engineering outcomes, find their blind spots, and measure whether each change actually improves them.
The goal is simple: know how well an agent works on your software, why it fails, and whether the next version is better.
Agent performance changes as models, tools and codebases change. Keep measuring after deployment.
Measure what the agent catches, what it misses, and what humans still add.
New model, prompt, tool or context? Run it against the same benchmark and measure the difference.
Ground truth comes from your repositories, engineers and production outcomes. An LLM should not grade its own homework.
Reduce human review where the evidence says it is safe. Keep people in the loop where they still add value.


LogicStar was founded in 2024 by engineers and researchers from DeepCode, Snyk, ETH Zurich and INSAIT. We have spent years working on code analysis, AI for software engineering and coding agents.
That work exposed a new problem. Agents can now write and review meaningful amounts of code, but teams still struggle to answer basic questions with data. How good is this agent on our code? What does it miss? What do humans still catch? Did the latest model, prompt or tool actually make it better?
LogicStar turns those questions into measurements using repository history, engineer actions, replayable benchmarks and production outcomes.

Martin is a full professor at ETH Zurich and one of Europe’s leading AI researchers, with 200+ publications spanning AI, quantum computing, and programming languages. He has co-founded five deep tech startups (including two exits) and launched INSAIT, raising over $280M to drive AI innovation.
Our research covers repository-level coding tasks, real bug fixes, security, refactoring and program analysis.We use the same approach with software engineering agents. Build the benchmark from the software the agent actually works on. Measure the gaps. Test changes against the same tasks. Keep monitoring as the agent and codebase change.


We’re not just following the AI revolution.
We’ve helped lead it.

LogicStar benchmarks software engineering agents on your code, finds their blind spots, and measures whether changes to models, prompts and tools improve the result. Keep measuring as the agents and code change.