Closing the Agentic Coding Loop with Self-Healing Software
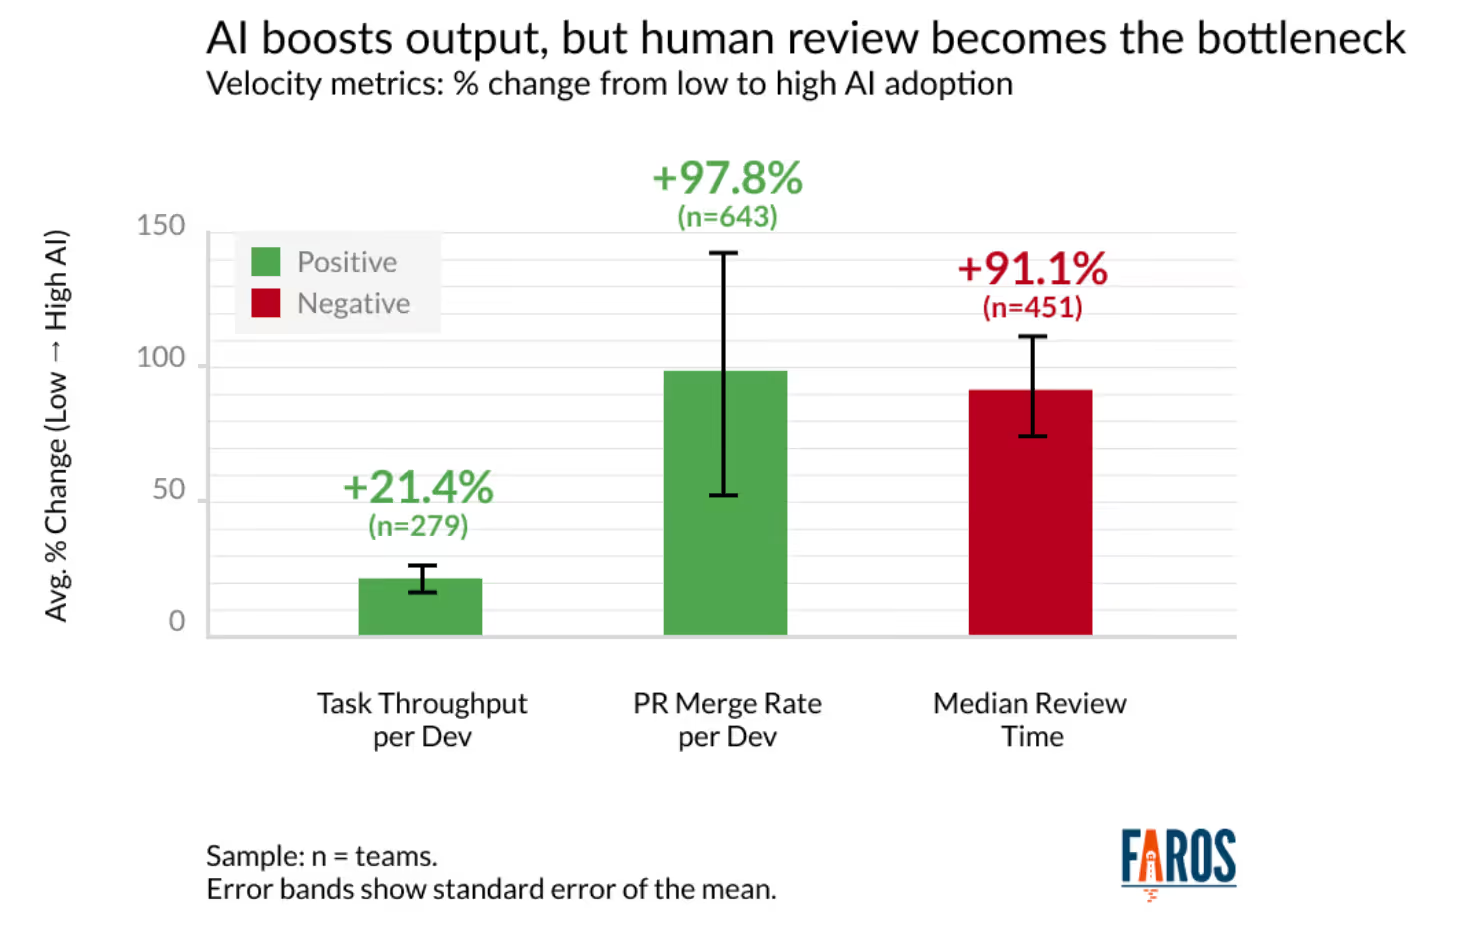
Over the past year, agentic coding tools like Cursor, Claude Code, and Codex have been adopted at remarkable speed. They already account for roughly 20% of public GitHub PRs [1] and teams using them report up to 50% productivity gains [2] in the early phases of adoption. But as review workloads spike and larger, more complex changes land faster than teams can absorb them, code quality begins to slip. The long-term benefits are far less clear.
In this post, we examine why today’s AI-assisted development workflows hit a wall and how Self-Healing Software can break through it.
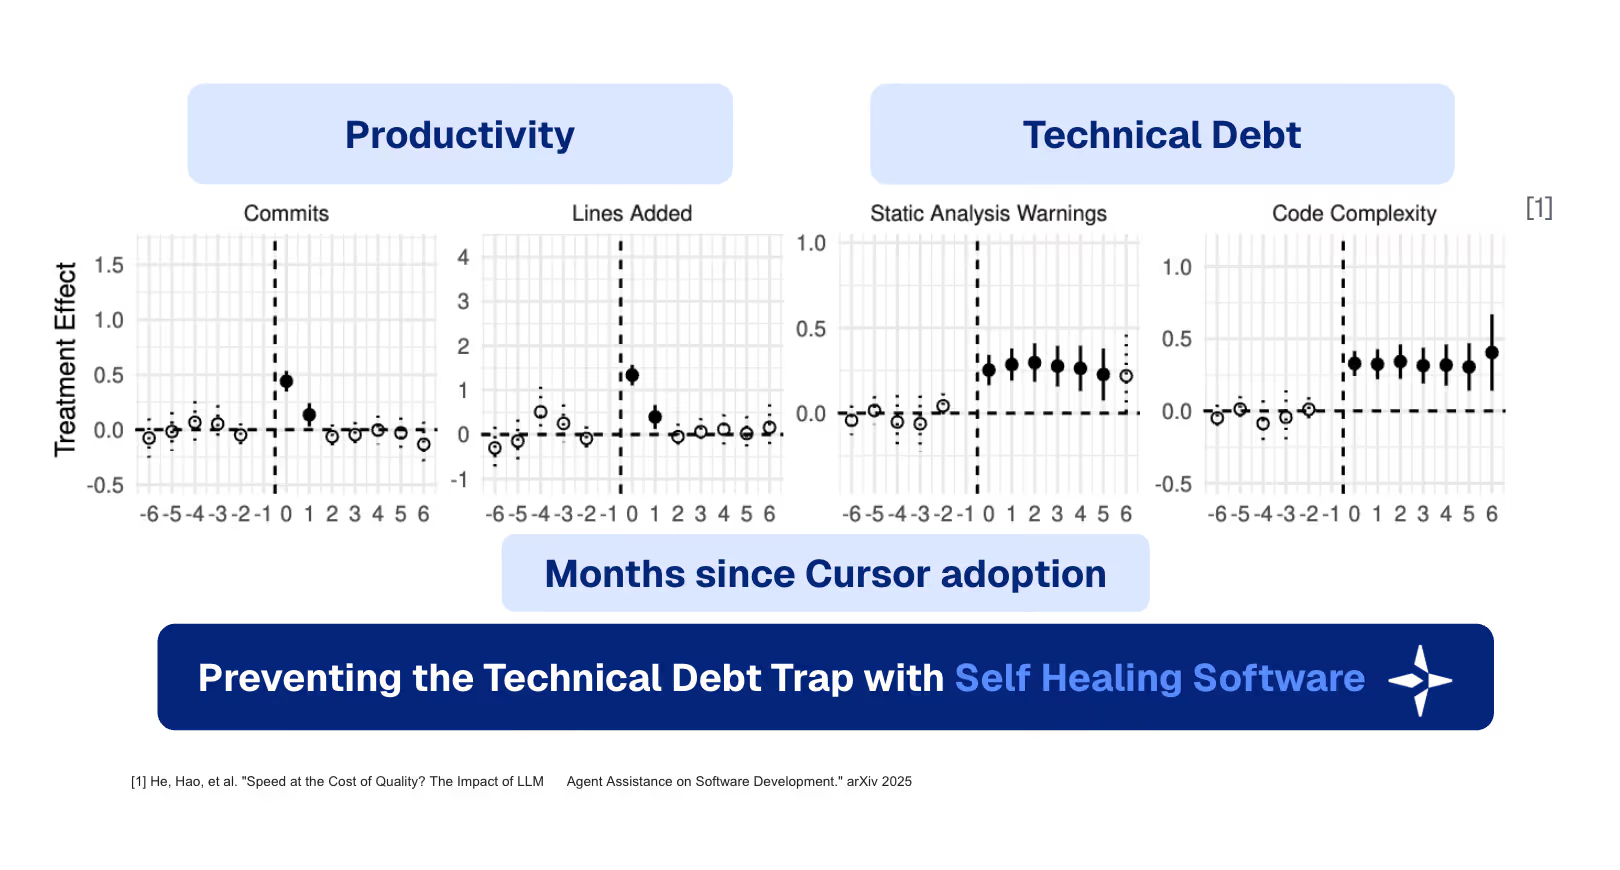
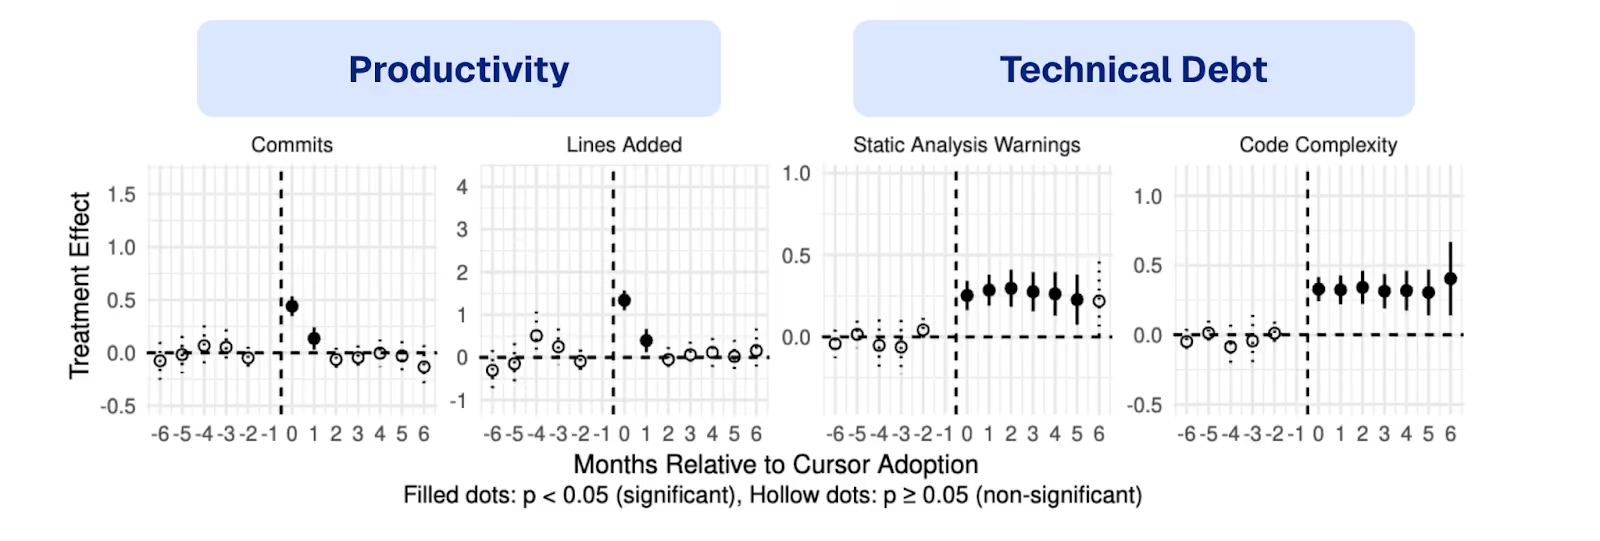
A recent CMU study [3] analyzing over 800 GitHub repositories that adopted Cursor identified a consistent pattern:
3–5× more code added in the first month
~30% increase in static analysis warnings
~40% increase in code complexity
After two months, velocity returned to baseline, while technical debt indicators stayed high
The takeaway is clear: when software can be produced faster than it can be reviewed, tested, and consolidated, quality becomes the limiting factor.
[3] He, Hao, et al. "Speed at the Cost of Quality? The Impact of LLM Agent Assistance on Software Development." arXiv 2025
Why Speed Alone Isn’t Enough
Agentic coding tools don’t just help developers write code faster; they encourage writing more new code.
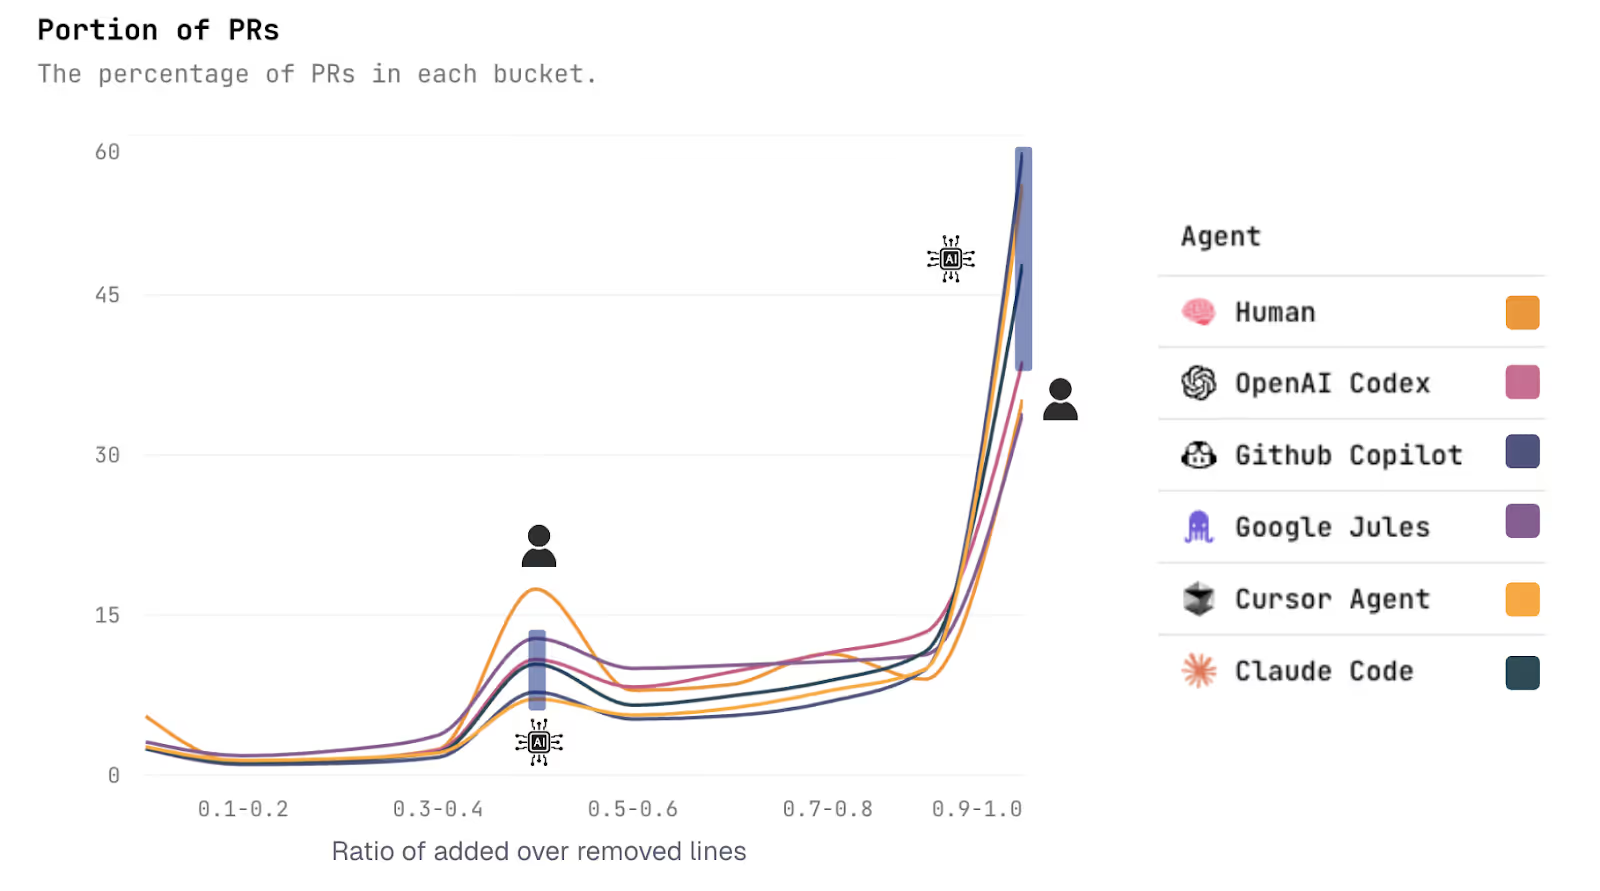
Analysing all public PRs on GitHub over the last 6 months, we find that AI-generated PRs tend to add significantly more lines than human-authored ones [1]. This is not just because LLMs generate verbose solutions. It reflects a deeper architectural problem:
Understanding and reusing existing code requires a lot of codebase context
Code agents can’t persist this context across problems, but have to gather it from scratch every time
Generating new code is often easier for the agent than building this context
In parallel, human reviewers now face larger, more complex PRs. Review quality drops, subtle bugs slip through, and duplicated patterns proliferate. The result is predictable: a burst of short-term acceleration followed by a plateau, or even slowdown, as technical debt accumulates and the codebase becomes harder to navigate and context more difficult to gather [3].
How Self-Healing Applications Close the Loop
To achieve sustained acceleration, it isn’t enough for AI to write new features faster. We need AI that also maintains the ever-growing, ever-more-complex codebase.
This means building systems that can automatically:
Detect functional, security, and code-quality issues
Generate high-quality fixes
Validate these fixes for correctness and side effects
In other words, software must be able to self-heal. As a result, development velocity will not just spike briefly before grinding to a halt, but grow sustainably as features get added while issues get automatically resolved.
How LogicStar AI Fits In
At LogicStar, we build exactly this missing piece, a platform for self-healing applications.
Our platform continuously analyzes applications, identifies real issues, generates candidate fixes, and verifies them using rigorous programmatic reasoning. This enables applications to become increasingly resilient, even as AI agents generate more of the underlying code.
A key advantage of LogicStar’s approach is how we understand the codebase. While most code agents use simple search tools like grep to explore a codebase, LogicStar builds a static-analysis–driven knowledge graph of the entire codebase. This persistent representation captures data flows, control flows, invariants, and component relationships that traditional agents must rediscover from scratch on every run. As a result, LogicStar can reason about bugs and validate fixes with far greater efficiency, depth, and consistency.
By leveraging this understanding to give software the ability to repair itself, we turn AI-driven feature development from a short-lived boost into long-term, compounding productivity.
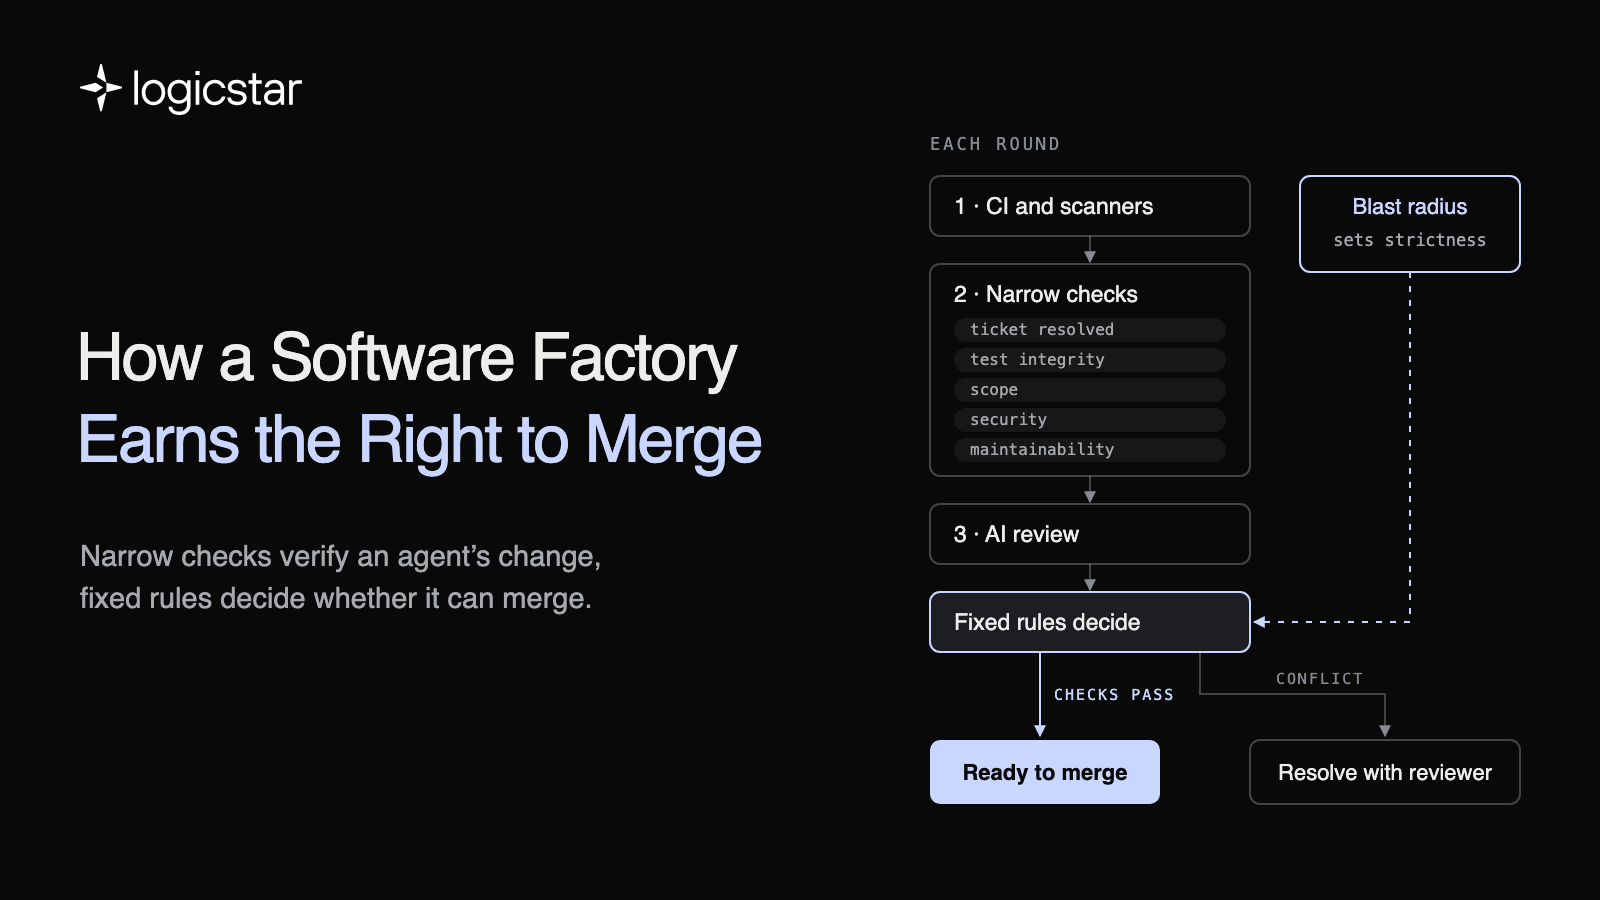
A coding agent can turn a ticket into a green pull request in minutes. We split the merge decision into narrow checks, let fixed rules decide, set the strictness by the blast radius of a change, and bring in a person only where the agent gets stuck.
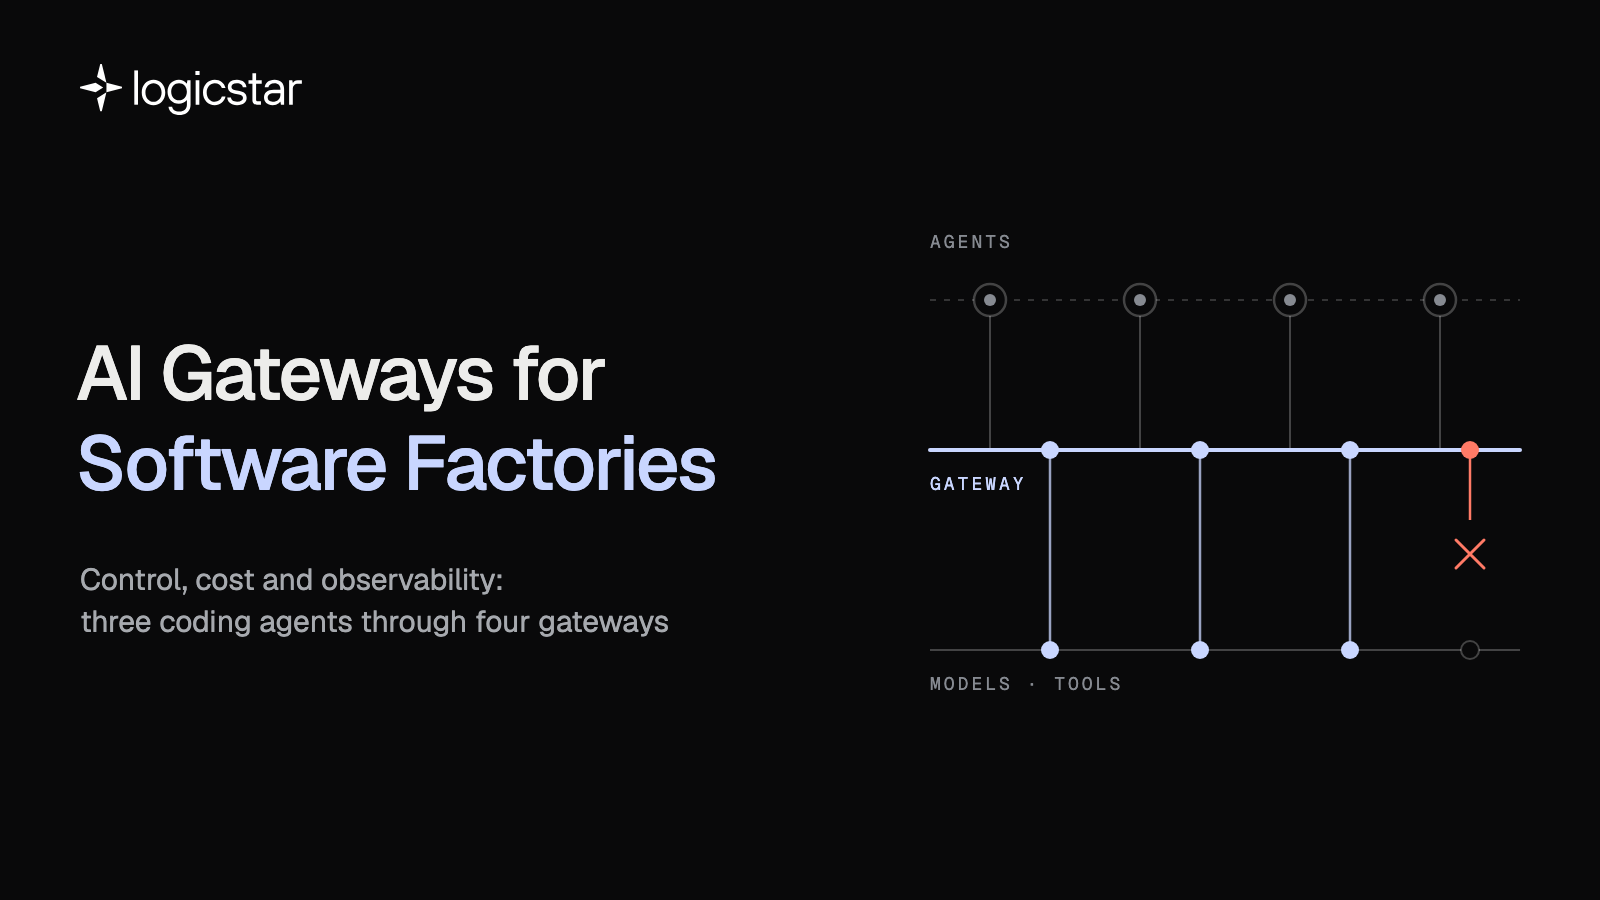
We ran three coding agents through four gateways to see what a gateway controls, what it measures correctly and where it misleads you, from budgets that overshoot to telemetry that leaks prompts and data residency set hop by hop.
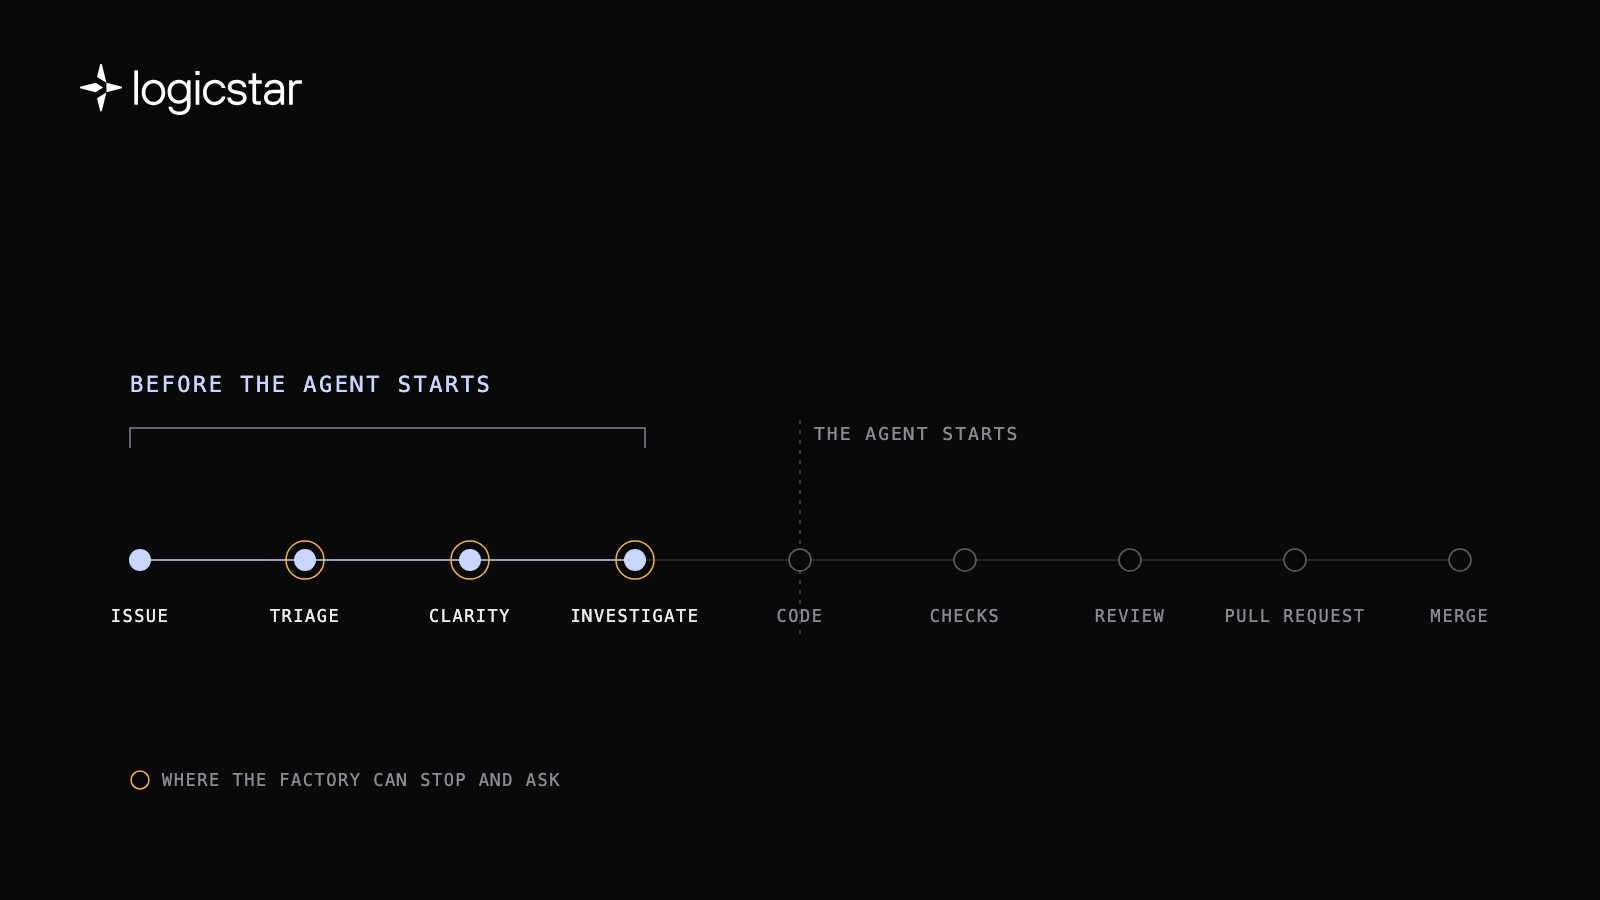
We compared a stronger model, a different agent, answers from the author and a read-only investigation before any code. On 19 fresh tickets, the investigation went ahead on 9 of 10 wanted changes and held back 7 of 9 requests an author had already declined.
We use cookies to run the site and understand how it’s used. You can accept all cookies or reject non-essential ones. See our Cookie Policy.
Cookie settings
By clicking 'Accept all cookies', you agree to storing cookies on your device to enhance site navigation, analyze site usage and assist in our marketing efforts as outlined in our cookie policy.